
AI voice agents that feed your Databricks Lakehouse
AgentVoice builds AI voice agents for enterprises that run on Databricks. When you license our voice engine, we deploy it into a cloud account you own, and every transcript, recording, call outcome, and insight writes directly to your Delta tables. Calls are handled with natural-sounding AI, and your call records stay in your environment.
A hosted voice platform keeps call data in its own systems, which gives a Databricks team one more silo to manage. The AgentVoice engine handles the hard real-time work, including live conversations with interruption handling, transfers, function calling, and natural speech. All persistent data flows into your Lakehouse through Delta Lake and Unity Catalog and is governed by your existing policies, so the voice engine sits inside your data platform.
Architecture
How it works
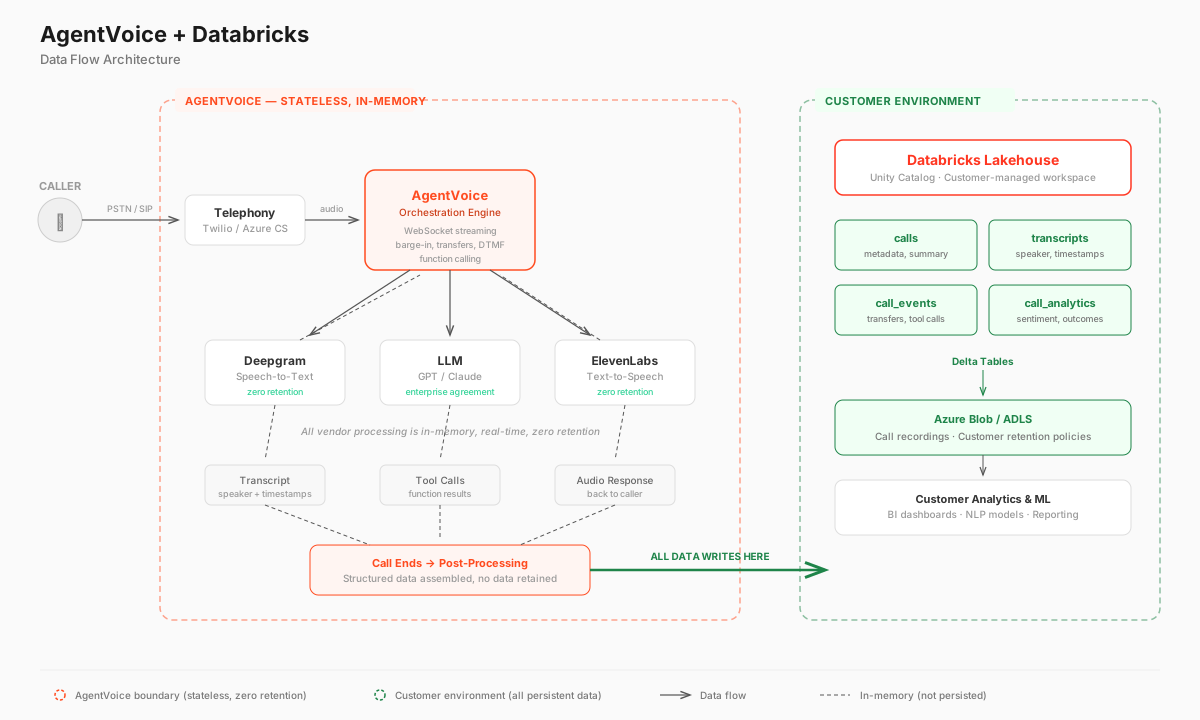
The AgentVoice engine operates as a stateless control plane for voice conversations, and your Databricks environment is the data plane. Under the platform license the engine runs in a cloud account you own, or we host it for you until you're ready to move it across. During a call, audio streams through the engine's orchestration layer in real time, using speech and AI vendors for each step (Deepgram for speech-to-text, ElevenLabs for text-to-speech, GPT or Claude for reasoning). Nothing persists in the engine after the call completes, and all durable data lands in your Lakehouse.
- A customer call arrives via PSTN, SIP, or WebRTC through your existing telephony (Azure Communication Services, Twilio, or carrier SIP trunk).
- The AgentVoice engine handles the live conversation with streaming speech recognition, LLM-powered reasoning with function calling and tool use, and natural speech synthesis, with barge-in and interruption handling.
- On call completion, structured data (transcript, metadata, call events, analytics, and outcome) writes to your Databricks workspace via the Delta Lake API and Unity Catalog.
- Call recordings write directly to your Azure Blob Storage or ADLS, which Databricks mounts natively as external locations.
The engine retains no customer data after call completion. Your governance policies, Unity Catalog permissions, and retention rules apply to all voice data the same way they apply to everything else in your Lakehouse.
Data Integration
What lands in your Lakehouse
The engine writes structured call data to your Databricks workspace using the Delta Lake API. You control the schema, permissions, retention, and access. We create standard tables on first connection, or map the output to your existing schemas.
- Calls table. Call ID, timestamp, duration, direction, phone numbers, agent ID, disposition, and AI-generated call summary.
- Transcripts table. Call ID, speaker role, timestamp, text, confidence score, and word-level timing. Available via real-time streaming or on call completion.
- Call events table. Call ID, event type (transfer, hold, function call, hangup, DTMF), timestamp, and structured payload for each event.
- Call analytics table. Call ID, sentiment scores, topic classification, entity extraction, intent detection, and outcome label.
Call recordings
Audio recordings write directly to your Azure Blob Storage or ADLS, which Databricks mounts natively as external locations. Recordings are governed by your existing Azure storage policies for retention, encryption, and access control. The engine does not keep copies.
Connection setup
You provide a Databricks workspace URL and a service principal with write access to your target schema. The engine authenticates through OAuth and writes call data to your Delta tables, and you can revoke that access at any time. We set up and test the connection as part of the deployment.
Security & Compliance
Stateless call processing
The engine processes voice in real time and retains no customer data after call completion. All persistent data writes to your Databricks workspace. The orchestration layer is stateless and handles the live conversation in memory, whether it runs in your cloud account or ours, then delivers the results to your environment.
Speech and AI vendors
We choose the speech and AI vendors in the stack with your data policies in mind and configure each vendor's retention settings during deployment. Deepgram handles speech-to-text. ElevenLabs handles text-to-speech. Azure OpenAI can provide LLM reasoning inside your own Azure subscription, with tenant-isolated deployments, private networking, and regional data residency.
Your governance applies
Call data in your Lakehouse is governed by your Unity Catalog permissions, retention policies, and access controls. We don't introduce new governance requirements. For organizations using Databricks compliance profiles for HIPAA, PCI, or similar standards, voice data falls under the same protections as the rest of your Lakehouse.
Security review documentation
For procurement and security reviews, we provide a complete data flow diagram showing every system involved in a call, what data passes through each system, what persists, and what doesn't. The only external touchpoints are the speech and AI vendors, and the diagram shows what each one receives.
What your agent can do
During the call
- Natural Voice Conversations. Text-to-speech via ElevenLabs with custom voice options and barge-in handling.
- Function Calling & Tool Use. Book appointments, look up records, check account status, process payments, and trigger workflows in external systems, all mid-conversation with structured outputs.
- Live Transfers & Escalation. Handoff to human agents with full conversation context. Warm transfers, cold transfers, and queue routing with complete interaction history attached.
- Contextual Intelligence. Agents access caller history, CRM data, and previous interactions to personalize every conversation before it starts.
- Interruption Handling. Callers can interrupt mid-sentence and the agent responds naturally. No awkward pauses, no talking over each other, no waiting for the AI to finish before speaking.
After the call
- Lakehouse Analytics. All call data lands in Delta tables ready for your existing BI tools, Databricks SQL dashboards, and ML workflows. No ETL pipelines to build.
- Transcript Search & Analysis. Full conversation transcripts with speaker roles, timestamps, and confidence scores. Query with SQL, run NLP models, or build search indexes natively in Databricks.
- Structured Outcomes. Every call produces a structured outcome, such as appointment booked, lead qualified, issue resolved, or escalated to a human. Feed these directly into ML models and reporting dashboards.
- Workforce Intelligence. AI-handled call volumes, resolution rates, and sentiment trends flow into your Lakehouse for capacity planning and performance analysis alongside human agent metrics.
Use Cases
Healthcare Systems
- AI voice agents handle appointment scheduling, prescription refill requests, insurance verification, and patient intake calls, with patient records kept in the customer's own environment
- All patient interaction data flows directly to the customer's Databricks workspace, under the compliance controls they already run there. Call recordings are stored in the customer's ADLS with their retention policies
- Compliance teams review AI call transcripts using existing governance workflows in Unity Catalog, with the same audit controls applied to all other regulated data
Financial Services
- Voice agents handle account inquiries, transaction verification, fraud alert callbacks, and loan status updates with real-time function calling for account lookups and transaction processing
- Every interaction is recorded, transcribed, and stored in the customer's Lakehouse for audit trails and regulatory compliance. Complete call records for dispute resolution and examiner requests
- Sensitive calls requiring licensed advisors or complex judgment escalate to human agents with full conversation context and customer data attached
Enterprise Contact Centers
- AI agents absorb tier-1 inquiries (account lookups, order tracking, scheduling, FAQ resolution) while routing complex issues to human agents with full context
- Handle peak periods without adding headcount. When volume drops, AI capacity scales back with no severance, no offboarding, and no impact on your permanent team
- AI and human agent metrics live in the same Lakehouse for unified reporting, capacity planning, and continuous improvement through ML models trained on call outcome data
Insurance
- Voice agents handle claims intake, policy inquiries, coverage verification, and first notice of loss calls, producing structured data (claim details, policy numbers, incident descriptions, caller sentiment) that writes directly to Delta tables
- Structured claims data feeds directly into processing pipelines and fraud detection models without manual data entry or transcription
- Complete call records for regulatory compliance, dispute resolution, and quality assurance across the full claims lifecycle
The AgentVoice engine compared with a self-built open-source stack
One alternative is for enterprises to deploy open-source models (Qwen, Whisper, etc.) on their own infrastructure for voice agents. Reference architectures exist, but they require building and maintaining an edge voice gateway, a separate ASR service, a separate TTS service on GPU, model conversion pipelines, manual barge-in logic, audio encoding/decoding, and a WebRTC media server. All of that is before you get a single production call working. The AgentVoice engine also runs on your own infrastructure, so the real choice is between building that voice stack yourself and licensing one that already handles production calls.
Once that stack works, your ML engineering team owns the edge gateway, ASR deployment, TTS deployment, model conversion pipeline, and all the glue code between them. That's engineering time spent maintaining voice infrastructure, and it comes out of the work the team was hired to do.
What the AgentVoice engine gives you
- Production-tested orchestration. WebSocket streaming, barge-in, interruptions, transfers, hold logic, DTMF, and function calling, all already running on production calls.
- Commercial speech and reasoning models. ElevenLabs TTS, Deepgram STT, and GPT or Claude for reasoning.
- Your data in your cloud. Records, transcripts, and recordings sit in your own Databricks workspace and storage, in your region, under your retention policy.
- Source code you hold. The code lives in your own GitHub organization, and your team can change it without waiting on our roadmap. We can keep operating the engine, your team can, or we host it for a monthly management fee.